Designing a Rule Engine That Scales with Your Factory
Industrial rule engines usually begin with a straightforward requirement:
"Send an alarm if this tag exceeds that value."
The problem is that real plants rarely stop there. Within a short period, teams usually need duration checks, shift-aware conditions, context overrides, cross-device correlation, ERP/CMMS actions, and safe rollout of logic changes. A rule engine that works for a pilot can become hard to operate once these requirements accumulate.
This article focuses on the design choices behind a production-facing industrial rule engine: authoring model, execution model, validation workflow, and operational safety boundaries. The exact throughput and latency you can achieve depend on workload shape, rule complexity, hardware, and whether the evaluation path stays local or depends on external systems.
- Hybrid authoring: Declarative rules plus code for advanced cases
- Local execution: Lower latency when decisions stay on the gateway
- Operational guardrails: Review, test, and rollback discipline required
Outcomes depend on workload profile, hardware capacity, and deployment topology.
The Problem with Traditional Rule Engines
Rule engines become difficult when the problem is no longer a single threshold.
Challenge #1: Scope Growth
A simple alarm often becomes a stateful policy:
- alert only if the condition persists for a duration
- suppress the alarm during setup or maintenance windows
- escalate immediately when a harder limit is crossed
Challenge #2: Cross-Device Context
Many industrial decisions depend on more than one signal. "Machine A is warm" is not enough; the logic may also need line state, upstream availability, downstream congestion, or work-order context from a business system.
Challenge #3: Load and Determinism
As device count and rule count increase, the cost of polling, re-checking shared state, and calling external systems grows quickly. A design that relies on frequent database queries or broad recomputation will usually degrade under bursty telemetry.
Challenge #4: Change Management
Production logic needs a lifecycle. Teams typically need draft rules, staged validation, promotion to specific gateways, and a clear rollback path if false positives or unintended writes appear.
The Proxus Approach: Rules, Pipelines and Functions
Proxus splits this work into a few clearly bounded tools, all configured on the hub and run on the Edge Gateways. (If your team builds this logic in Node-RED today, Proxus compared with Node-RED sets a flow toolkit against a governed platform.)
Expression and Anomaly Rules (No Code)
Rules are useful when the logic is explicit, bounded, and easy to review:
- expression rules for thresholds and conditions
- anomaly rules for Z-score, IQR, moving average, rate of change, drift, flatline and gap detection
- evaluation in real time or on a schedule
- actions such as alerts and notifications
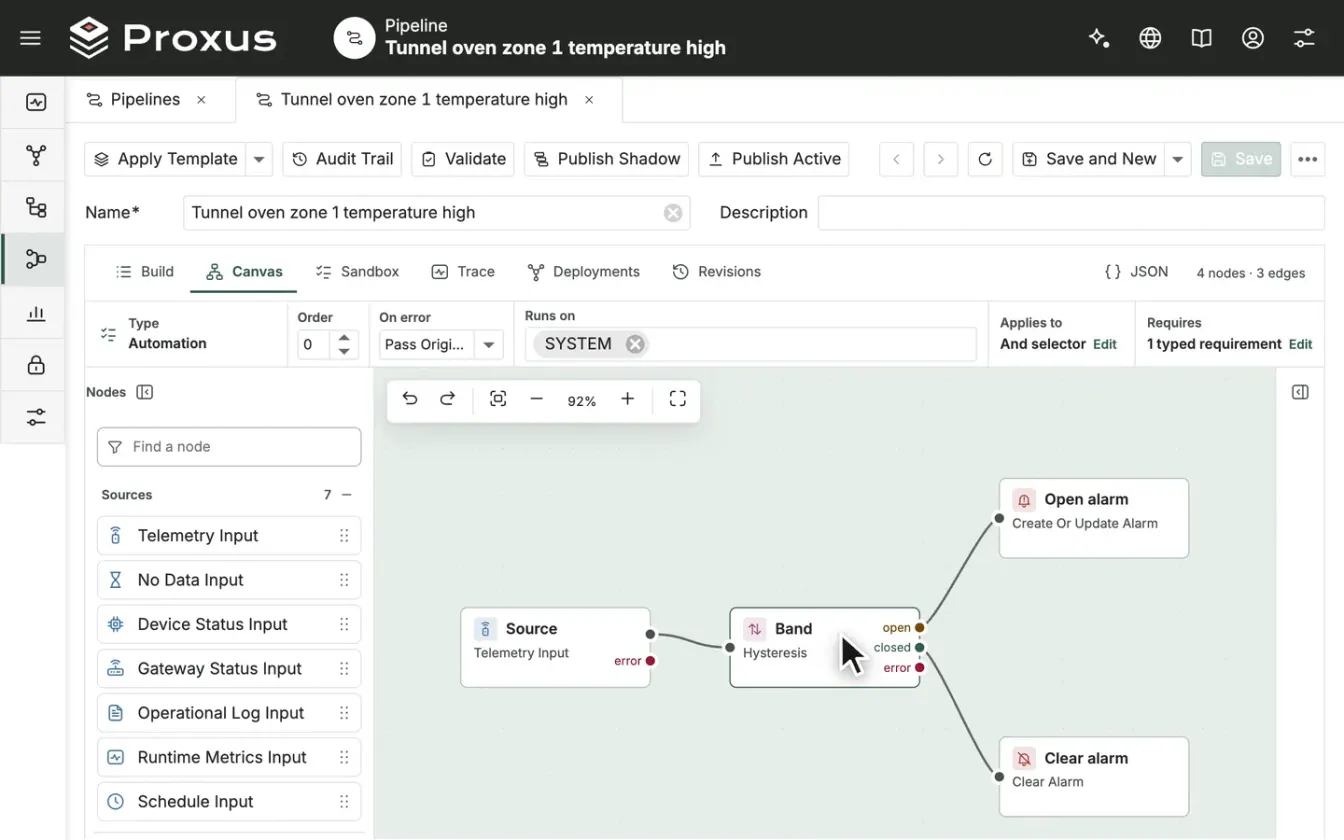
Rules run at the edge and keep running when the network is down. The advantage is not just accessibility: a declarative rule is also easier for operations, controls, and software teams to review together before it goes live. Pipelines cover the shaping work around them (convert, scale, rename, filter, route) and keep comparable revisions, so a change can be reviewed against the previous version.
C# Functions for Advanced Cases
Some cases genuinely need code. In Proxus that code is a C# function written against the Proxus SDK, built and deployed from the hub:
- multi-device correlation over a time window
- derived state calculations
- statistical smoothing or anomaly scoring
- transformations that are awkward to express as nested visual conditions
The important design principle is not "code everywhere." It is using scripting only where the visual model becomes harder to reason about than the logic itself.
Example Decision Pattern
Whether the logic is authored visually or in code, the decision path should still read like an operating policy:
IF temperature exceeds the warning threshold
AND the machine is in production mode
AND the condition persists for the configured duration
AND the line is not in a scheduled maintenance window
THEN publish an event, notify operations, and optionally create a maintenance task
That policy is easier to validate than an implementation full of runtime objects and SDK calls.
A Single Unified Execution Model
The main architectural value of a shared runtime is operational consistency. Teams should not have to learn one deployment model for declarative rules and a different one for code.
In practice, scalability depends on a few factors:
- how often the triggering tags change
- whether the rule works from local in-memory state or needs external I/O
- whether the rule is per-device, cross-line, or cross-site
- whether the output is a local event, a broker publish, or a remote API call
Rules that stay local and evaluate against already-contextualized telemetry will usually perform better and more predictably than rules that depend on synchronous remote systems.
The implementation goal is therefore straightforward:
- keep the critical evaluation path local
- publish state changes rather than repeatedly poll for them
- separate live decisioning from heavier historical analytics
- isolate expensive integrations so they do not block the core rule loop
Validation, Rollout, and Safety Boundaries
The operational model matters as much as the rule syntax.
Validation Workflow
A practical industrial workflow usually includes:
- author the rule centrally
- run it against test or shadow data
- review alert quality and false positives
- promote it to selected gateways
- keep a rollback path to the previously approved version
This is especially important for rules that generate maintenance work orders or trigger write-capable downstream actions.
Safety Boundaries
Even a well-designed rule engine should not absorb every kind of industrial logic.
- Safety PLC logic remains in the safety layer.
- Hard real-time interlocks remain in deterministic control layers.
- Enterprise-facing orchestration, condition monitoring, and alerting are better candidates for a gateway rule engine.
Security Boundaries
If scripting is supported, it should operate under controlled execution boundaries, explicit review, and bounded permissions. Public marketing content does not need to expose internal class names or runtime limits to explain this; the important point is that user-authored logic should be reviewable, testable, and constrained.
When Complex Rule Engines May Be Overkill
In my experience, rule engines are sometimes overengineered for the problem at hand. Consider deploying simpler architectures in these scenarios:
- Hard Real-Time Safety Control: A safety-critical Emergency Stop or hardwired interlock should not rely on a rule engine, however robust. These decisions must remain in certified Safety PLCs hardwired with no software dependencies.
- Simple PLC-Resident Logic: If your automation needs are adequately served by native PLC logic (Boolean conditions, timers, counters), adding a rule engine introduces unnecessary operational complexity and maintenance burden.
- Single-Asset, Single-Criteria Plants: Factories with 3-5 simple threshold alarms may not justify the administrative overhead of a full rule engine platform. A basic SCADA alarm may suffice.
- Immature or Unstable Data Sources: If your tags are not consistently available, naming conventions are chaotic, or data quality is poor, a rule engine will amplify frustration rather than solve it. Stabilize your UNS first; Unified Namespace architecture: a practical guide covers the naming and quality rules.
When this may not be suitable
- Lower-frequency telemetry may not justify full distributed complexity.
- Small single-line plants may prefer simpler architectures first.
- Strict legacy constraints may require phased adoption.
- Safety-critical closed-loop control should remain in PLC/Safety PLC layers.
Results vary with workload, hardware, and topology.
Frequently Asked Questions
When should I use expression rules vs. C# functions?
Use expression and anomaly rules when logic can be expressed clearly as thresholds, notifications, scheduled triggers, and bounded conditional workflows. Use code when requirements need multi-device correlation, stateful computations, external calls, or specialized libraries. Choose per rule from testability, review ownership, deployment controls, and failure impact rather than an assumed percentage.
What latency can I expect from edge rule evaluation?
Latency depends primarily on how much data the rule touches and whether the execution path stays local. A simple gateway-local threshold or duration rule can evaluate quickly, while a rule that waits on an external HTTP endpoint will inherit network latency and downstream system variability. Safety-critical rules such as emergency stops should remain in deterministic PLC or Safety PLC layers; gateway rules are better suited to monitoring, orchestration, and enterprise-facing actions.
How do I test rules without affecting production?
A practical pattern is to run the new rule first on a test gateway that reads the same sources, with its actions routed to a test channel instead of the people on shift. Watch the alerts it would have raised for long enough to cover the normal cycle of the process (shifts, changeovers, weekends), then promote it. In Proxus, configuration changes are recorded in the audit trail, pipelines keep comparable revisions, and the Trend workspace shows the stored alert moments next to the values. Note that it shows the alerts that actually fired; it does not replay a new detector over history. The exception is a rule proposed through the AI Assistant: before you approve it, the assistant tries it on stored data and shows how often it would have fired (AI Assistant and agent access).
Can rules trigger on OPC UA data sources?
Yes. The rule engine operates on tags within the Unified Namespace, regardless of their original source protocol. If an OPC UA tag is mapped to the UNS via the Proxus Edge Gateway, it becomes a first-class trigger just like Modbus, S7, or native MQTT tags. The rule does not know or care about the upstream protocol.
How do rules synchronize across multiple Edge Gateways?
Rules are authored centrally on the hub and delivered to specific edge gateways; a gateway keeps no configuration of its own. Each gateway evaluates its rules independently against its local tags. There is no distributed consensus protocol, which is deliberate: a decision does not wait on the network, and rules keep running when the link is down. For cross-site comparison (e.g., OEE across plants), work from the historian and dashboards on the hub, where every site's data already lands.
Conclusion: Rules as Production Assets
In Proxus, automation rules are not an afterthought bolted onto a visualization tool. They are engineering assets: defined centrally, delivered to the gateways that need them, recorded in the audit trail, and run at the edge where they keep working through network outages.
Whether you need a simple threshold alert or a C# function that correlates several signals, treat each rule the same way: write the policy down, test it against real data, and keep the previous version ready.
References
- IEC 61131-3 - International standard for PLC programming languages, defining structured text (ST) and function block diagram (FBD) patterns that inspired industrial rule engine design. IEC 61131
- Charles Forgy, "Rete: A Fast Algorithm for the Many Pattern/Many Object Pattern Match Problem" (1982) - The foundational algorithm behind many production rule systems, relevant to understanding rule evaluation performance.
- Carl Hewitt, "A Universal Modular Actor Formalism for Artificial Intelligence" (1973) - The mathematical foundation of the Actor Model, a common basis for concurrent rule runtimes.
- OPC Foundation - OPC UA Alarms & Conditions - Specification for industrial alarm management via OPC UA, relevant as a data source for rule engine triggers. opcfoundation.org
Explore how the Proxus Rule Engine integrates with your existing architecture by reading our Edge Computing Patterns guide, or see how rules drive IT/OT convergence and predictive maintenance workflows.
Last updated August 6, 2026